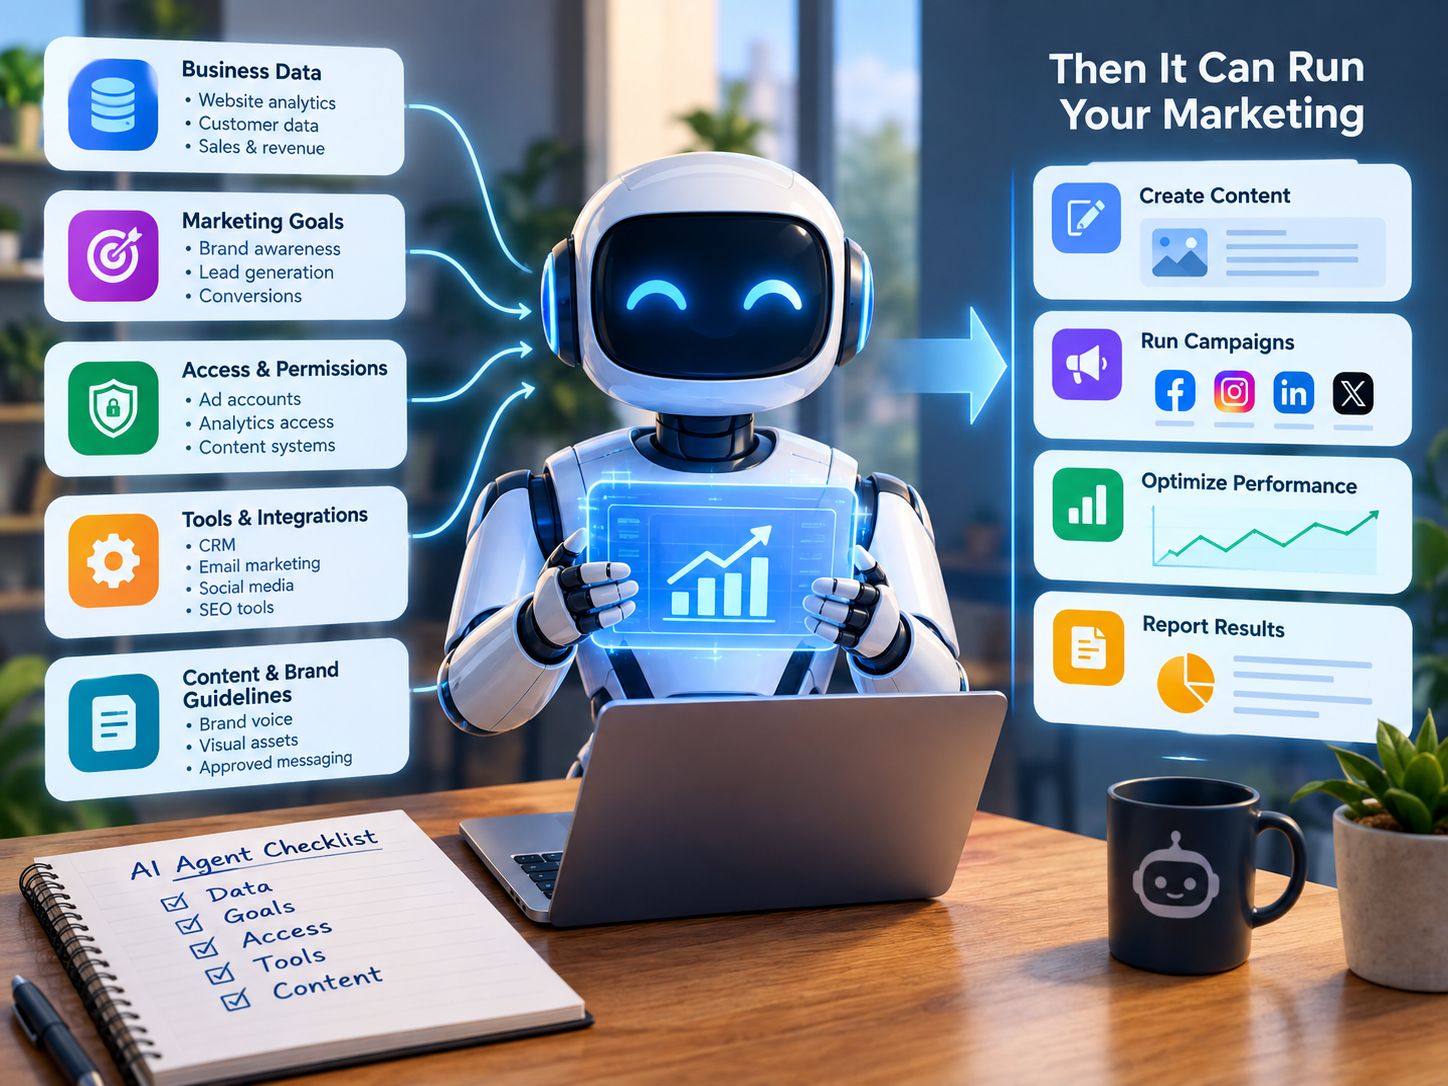
AI agent in marketing – artistic impression. Image source: Alius Noreika / AI
Teams evaluating an AI marketing agent usually start with the model. They compare reasoning benchmarks, context windows, and tool use. That comparison matters less than most buyers expect.
What decides the outcome is what the agent receives on day one. An agent without brand context writes generic copy. An agent without channel access cannot publish. An agent without an approval gate ships work nobody reviewed.
Marketing makes this harder than most functions. The output is public. It gets judged on taste. It has no clean pass condition.
This piece covers what has to exist before an agent runs marketing work. It shows where readiness breaks in practice. It ends with a checklist for deciding whether to start.
Why Marketing Agents Fail for Reasons Unrelated to the Model
Most failed deployments get blamed on the model. The real cause usually sits further upstream. The agent was asked to own an outcome. It was handed only the tools for a task.
The Gap Between Writing and Running
Writing produces a draft when somebody asks for one. Running means choosing the work and sequencing it. It also means reporting what changed afterwards. That second job needs context no prompt supplies.
The difference shows up in the first week:
- A writing tool waits for a brief and returns copy.
- A running agent decides which page to build and why.
- A writing tool measures nothing after delivery.
- A running agent checks what moved and adjusts.
Teams often buy the first and expect the second. The disappointment that follows has nothing to do with output quality. It comes from a mismatch in scope.
Marketing Has No Deterministic Success Test
Consider the workflows your team already automates. An invoice either matches the purchase order or it does not. A support ticket either routes correctly or gets reassigned. Both carry a clean failure signal.
A landing page has no equivalent. It can be grammatical, on topic, and factually correct. It can still be wrong for the brand. Guardrails therefore matter more in marketing, not less.
The missing pass condition means a person supplies judgment. Your setup decides whether that person sees the work in time. Most teams learn this after an awkward draft goes live.
Why This Gets Misdiagnosed
The symptom is generic output. The instinct is to switch models or rewrite prompts. Both feel productive. Neither addresses the cause.
Check the inputs first:
- Positioning, and whether the agent can reach it.
- Customer definition, and whether it knows who to write for.
- Competitor claims, and whether it can see them.
- Success criteria, and whether anyone stated them.
A stronger model with the same inputs produces better written generic output. That is a real improvement in prose and no improvement in results.
What Has to Exist Before the First Run
Three things gate every marketing agent deployment. None is a technical problem. All are cheaper to fix before you start. Skipping them turns a pilot into a stalled project.
Business Context the Agent Can Read
An agent that guesses at positioning sounds like every competitor. Context has to be retrievable rather than remembered by your team.
At minimum the agent needs:
- Product and positioning, stated plainly where it can reach.
- Customer definition, so output aims at someone specific.
- Competitor set, which makes differentiation and comparison possible.
Where this lives matters less than whether it exists. Kite, an AI marketing agent built for Slack, reads the live site when it joins a channel. It then proposes the first piece of work itself. Nothing publishes until someone approves it in the thread.
Channel Access With Scoped Permissions
Access is where most deployments quietly stall. Teams grant everything or nothing. Both choices cause problems later.
Separate the permissions before the first run:
- Publishing destinations the agent may touch, named explicitly.
- Read access to analytics and search data, kept distinct from write access.
- Individual credentials rather than one shared login.
Shared logins are the common failure. They make it impossible to audit what changed. They also make it hard to revoke access cleanly.
An Approval Gate Matched to Blast Radius
Autonomy works better as a dial than a switch. Set it by consequence rather than by trust.
A workable default looks like this:
- Read only for research, audits, and recommendations.
- Draft and approve for anything public facing.
- Limited action for low-risk changes such as internal tagging.
High autonomy belongs in tightly bounded work. Public marketing output rarely qualifies. Move the dial once the output has earned it.
Two Readiness Scenarios
Readiness is easier to judge against examples than against principles. These two patterns cover most teams.
Wins Scenario: A Lean Team, One Goal, One Channel
What happens in the real world: a small business has a live website and one growth goal. One channel already brings visitors.
Why it works: context is retrievable, approval runs through one person, and success has a number attached.
Where it still needs care: the first published piece should pass review. Trust can come later.
Cracks Scenario: Several Brands, No Brand Guide, Shared Logins
What happens in the real world: three product lines and tone that lives in people’s heads. One marketing login serves the whole team.
Why it cracks: the agent cannot tell which brand it writes as. Nobody can trace what it changed.
The fix before starting: write the brand context down, then split the credentials.
The gap between these two scenarios shows up in national data. Census Bureau researchers found that 18% of firms used AI in a business function in late 2025. The figure rises to 32% when weighted by employment. Deployment into a specific function is still uneven.
Buying access is simple. Getting an agent into a function is harder. That step needs permissions, context, and a named owner. It is the part teams underestimate.
A Readiness Checklist
Use this before the first run rather than after the first problem. Each item takes an afternoon at most.
Start When
- Business context exists in a form the agent can retrieve.
- Channel permissions are scoped and named individually.
- One person owns approval for public output.
- The goal has a number attached to it.
Wait When
- Brand voice is undocumented and lives in conversation.
- Credentials are shared across several people.
- No approval owner has been named.
- Nobody agrees on what success looks like.
Four yes answers in the first list means you can start small. Any yes in the second list is worth fixing first. The fix is usually a document and a permissions change.
The Most Common Blocker
One item fails more often than the rest. Nobody owns approval.
Teams assume approval is obvious and it rarely is. The founder is busy. The person closest to marketing has no mandate. Work then sits in a queue waiting for a decision nobody was asked to make.
Name the approver before the first run. Give them a response window they can actually meet. A single named person beats a review committee at this stage.
Bottom Line
The model matters less than the context, access, and approval gates around it. Marketing agents fail on setup more often than on capability.
Pick one goal and one channel. Write your positioning where the agent can read it. Name the person who approves public work. Keep the dial at draft and approve for now.
That is roughly a week of preparation. It decides whether the next six months produce results. The alternative is a growing pile of drafts nobody ships.